Page 4 of 45

ONDC, Beckn, and VRM

This is important. Be there.

If we want VRM to prove out globally, we have to start locally. That’s what’s happening right now in India, using ONDC (the Open Network for Digital Commerce), which runs on the Beckn protocol.

ONDC is a happening thing:
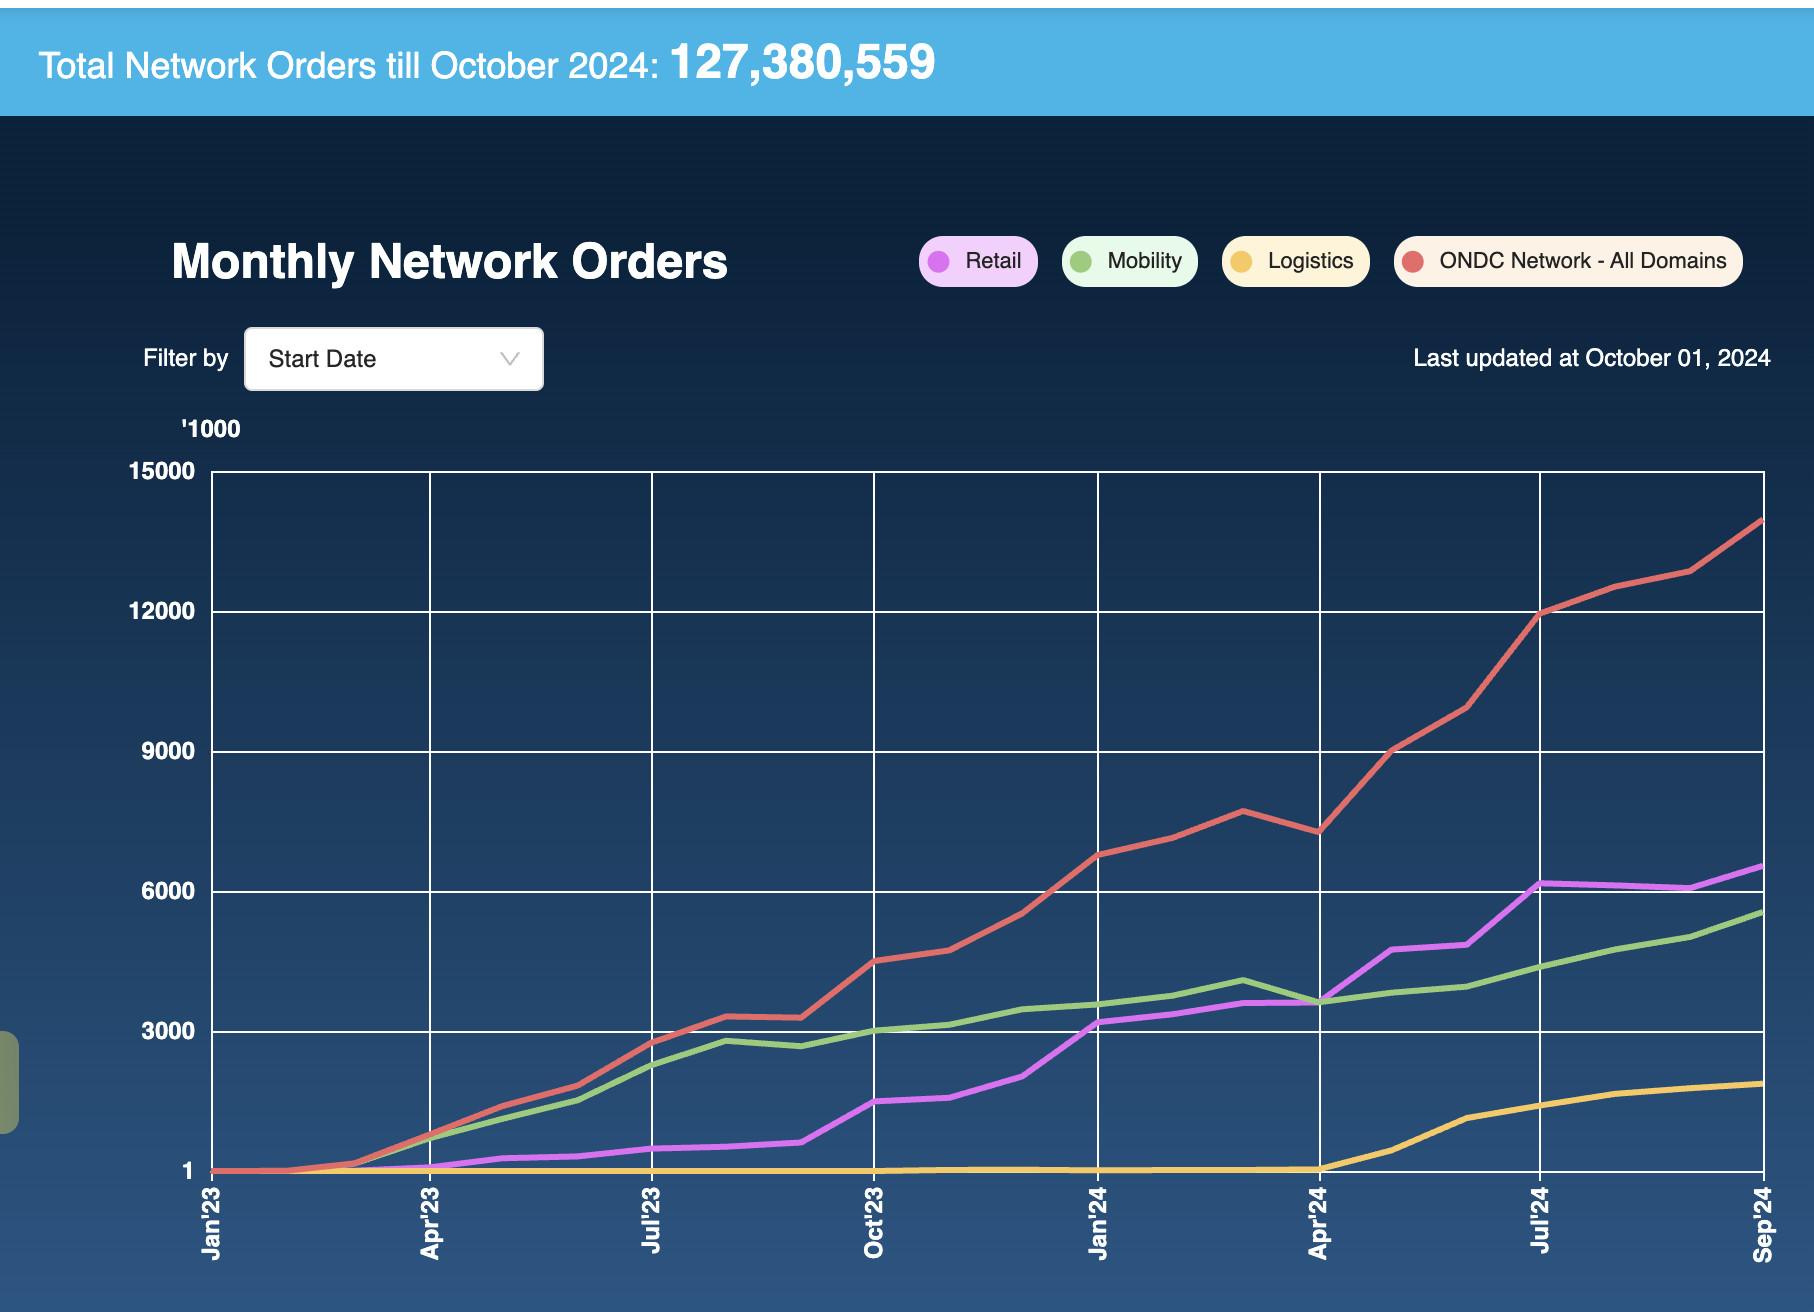
One big (and essential) goal for VRM is individual customer scale across many vendors.  ONDC and Beckn are for exactly that. Here is how kaustubh yerkade explains it in Understanding Beckn Protocol: Revolutionizing Open Networks in E-commerce:

Beckn protocol in the Real World
The Beckn Protocol is part of a larger movement toward creating open digital ecosystems, particularly in India. For example, the ONDC (Open Network for Digital Commerce) initiative in India is built using the Beckn protocol, aiming to democratize e-commerce and bring small retailers into the digital economy. The Indian government supports ONDC for making digital commerce more accessible and competitive.

Here are some practical examples of how the Beckn Protocol can be used in different industries:

1. Ride-Hailing and Mobility Services
Example: Imagine a city with multiple ride-hailing services (e.g., Uber, Ola, Rapido). Instead of using individual apps for each service, a user can use one app powered by the Beckn Protocol. This app aggregates all available ride-hailing services, showing nearby cars, prices, and estimated arrival times from multiple providers. The user can choose the best option, book the ride, and pay directly through the unified app.

Benefit: Service providers gain broader visibility, and users can easily compare services in one place without switching between apps.

https://becknprotocol.io/imagining-mobility-with-beckn/

2. Food Delivery Services
Example: A consumer uses a food delivery app that leverages Beckn to show restaurants from multiple food delivery services (like Zomato, Swiggy, and local food delivery providers). Instead of sticking to just one platform, the user sees menus from different services and can order based on price, availability, or delivery time.

Benefit: Restaurants get listed on more platforms, increasing their exposure, and users can find more options without hopping between different apps.

3. E-Commerce and Local Retail
Example: A shopper is looking for a product (like a phone charger) and uses an app built on the Beckn Protocol. The app aggregates inventory from big e-commerce players (like Amazon or Flipkart) as well as small local retailers. The user can compare prices and delivery times from both big platforms and nearby local stores, then make a purchase from the most convenient provider.

Benefit: Small businesses and local stores can compete with larger e-commerce platforms and reach a wider audience without needing their own app or website.

4. Healthcare Services
Example: A patient needs to book a doctor’s appointment but doesn’t want to manually search through different healthcare platforms. A healthcare app using Beckn shows available doctors and clinics across multiple platforms (like Practo, 1mg, or even independent clinics). The patient can choose a doctor based on location, specialization, and availability, all in one place.

Benefit: Patients get access to a larger pool of healthcare providers, and doctors can offer their services on multiple platforms through a single integration.

5. Logistics and Courier Services
Example: An online seller wants to ship products to customers but doesn’t want to manage multiple courier services. With an app built on Beckn, they can see delivery options from multiple logistics providers (like FedEx, Blue Dart, and local couriers) and choose the best one based on cost, speed, or reliability.

Benefit: Businesses can streamline shipping operations by comparing various logistics providers through one interface, optimizing for cost and delivery time.

6. Public Transportation
Example: A commuter is planning a trip using public transit in a city. Using a Beckn-powered app, they can view transportation options from multiple transit services (like metro, bus, bike-sharing services, or even ride-hailing). The app provides real-time schedules, available options, and payment methods across different transport networks.

Benefit: The commuter has a unified experience with multiple transportation modes, improving convenience and access to more options.

7. Local Services (Home Services, Repair, Cleaning)
Example: A user needs a home repair service (e.g., a plumber or electrician). Instead of browsing different service provider platforms (like UrbanClap or Housejoy), a Beckn-enabled app aggregates professionals from multiple service providers. The user can compare prices, reviews, and availability and book a service directly from the app.

Benefit: Service providers get access to more customers, and consumers can quickly find professionals based on location, reviews, and price.

8. Travel and Hospitality
Example: A traveler uses a travel booking app based on Beckn to find accommodations. The app aggregates listings from various hotel chains, Airbnb, and local guesthouses. The traveler can filter by price, location, and amenities, then book the best option without switching between platforms.

Benefit: Smaller accommodation providers can compete with big brands, and travelers get access to more choices across different platforms in one app.

9. Government Services and Civic Engagement
Example: A citizen uses a Beckn-enabled app to access multiple government services. They can apply for a driver’s license, pay taxes, and book a health checkup at a government hospital—all from one platform that integrates services from different government departments and third-party providers.

Benefit: Governments can offer a unified experience across various services, and citizens get easier access to public services without visiting multiple websites or offices.

He adds,

The ONDC (Open Network for Digital Commerce) initiative in India is built using the Beckn protocol, aiming to democratize e-commerce and bring small retailers into the digital economy. The Indian government supports ONDC for making digital commerce more accessible and competitive.

While it is nice to have government support, anyone anywhere can deploy open and decentralized tech, or integrate it into their apps and services.

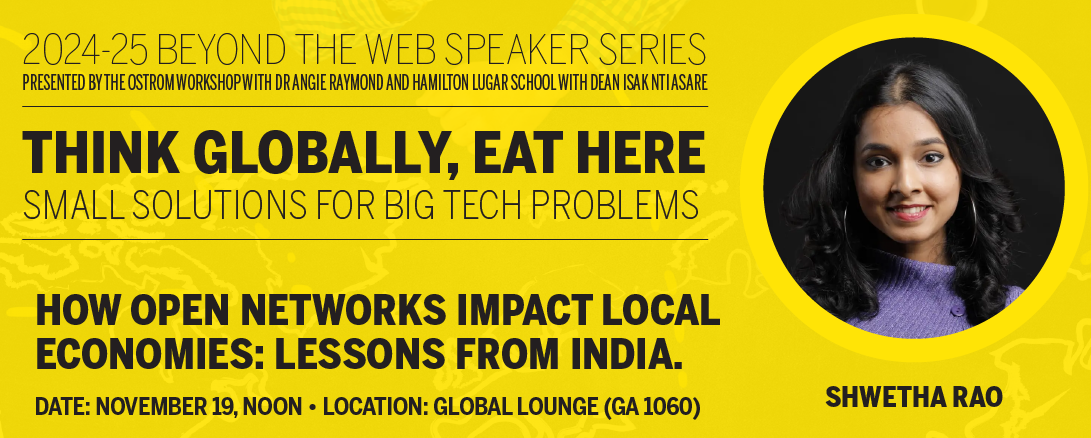
On Tuesday we’ll have a chance to talk about all this at our latest salon at Indiana University and live on Zoom. Our speaker, Shwetha Rao, will be here in person, which always makes for a good event—even for those zooming in.

So please be there. As a salon, it will be short on lecture and long on dialog, so bring your questions. The Zoom link is here.



VRM Day and IIW next week

A pano from VRM Day in April 2015

VRM Days always happen the day before IIW starts, twice each year. Usually, we have about 50 registered and 30 showing up. (Some are online, though we’d rather have their bodies in the room.)  For the VRM Day this coming Monday, we’re expecting more than 100 people. So, like Sheriff Brody said in Jaws, we need a bigger room.

And we have one. So that’s good. Logistics will be challenging, but we’re on top of them.

IIW is also close to sold out. Last I checked, there were just nine tickets left.

Here is copy from our Eventbrite page as it now stands:

The Main Thing

At this VRM Day, Ben Moskowitz, VP Innovation and Ginny Fahs, Director of Product R&D at Consumer Reports will lead discussion of some of their early R&D concepts around a new approach to customer service: one in which personal AI agents represent customers’ best interests.

This is CX (Customer Experience) re-imagined and re-implemented in ways that are no less real and human but far more intelligent, mutually informative, and useful than what all of us have experienced thus far in the Digital Age. CR is looking for feedback and collaboration as they move forward. They plan to participate in IIW as well.

As usual, everyone who wants to share what they’re working on in the VRM space will have time to present, discuss, and prep for IIW.

Schedule

Morning:

  • 9am – Noon. Consumer Reports presentation and discussion (on the above)

Lunch

  • Noon – 1:30 (Sports Page or Zareen’s (diagonal across the intersection)

Afternoon

  1. Adrian Gropper on HIE of One, Medical AI Assistant (MAIA) and personal AI in health care
  2. Joe Andrieu on the Digital Fiduciary Initiative
  3. Cryptid / KwaaiNet demo
  4. Iain Henderson on Data Pal
  5. Richard Whitt on GliaNet Alliance
  6. Customer Commons on IEEE P7012
  7. Paul Trevithick (Mee.Foundation) on Private Advertising
  • Discussion on any or all of the above

  • Listing planned IIW sessions

Subject to change, of course.

Since we have a lot to cover, please be there at 9am sharp, and be back from lunch at 1:30.

Note that there are only three lunch places nearby. Cucina Venti is good but relatively expensive and service is slow. Sports Page is makes good sandwiches and has lots of picnic tables. It’s where most of us usually go. Haven’t tried Zareen’s, behind the Sports Page, where Sunny Bowl and other restaurants used to be. It has “familiar & innovative halal spins on Indian & Pakistani cooking.”


On Intentcasting

The cover page of the Weekend Review section of The Wall Street Journal, July 20, 2012

On July 9, 2012, not long after The Intention Economy came out, I got word from Gary Rosen of The Wall Street Journal that the paper’s publisher, Robert Thomson, loved the book and wanted “an excerpt/adaptation” from the book for the cover story of  the WSJ’s Weekend Review section. The image above is the whole cover of that section, which appeared later that month.

In the article I described a new way to shop:

An “intentcast” goes out to the marketplace, revealing only what’s required to attract offers. No personal information is revealed, except to vendors with whom you already have a trusted relationship.

I also said that this form of shopping—

…can be made possible only by the full empowerment of individuals—that is, by making them both independent of controlling organizations and better able to engage with them. Work toward these goals is going on today, inside a new field called VRM, for vendor relationship management. VRM works on the demand side of the marketplace: for you, the customer, rather than for sellers and third parties on the supply side.

The scenario I described was set ten years out: in 2022, a future now two years in the past. In the meantime, many approaches to intentcasting have come and gone. The ones that have stayed are Craigslist, Facebook Marketplace, Instacart, TaskRabbit, Thumbtack, and a few others. (Thumbtack participated in the early days of ProjectVRM.) We include them in our list of intentcasting services because they model at least some of what we’d like intentcasting to be. What they don’t model is the full empowerment of individuals as independent actors: ones whose intentions can scale across whole markets and many sellers:

Scale gives the customer single ways to deal with many companies. For example, she should be able to change her address or last name with every company she deals with in one move—or to send an intention-to-buy “intentcast” to a whole market.

Should we call the sum of it “i-commerce“? Just a thought.

Back to the Wall Street Journal article. It is clear to me now that The Customer as a God would have been a much better title for my book than The Intention Economy, which needs explaining and sounds too much like The Attention Economy, which was the title of the book that came out ten years earlier. (I’ve met people who have read that one and thought it was mine—or worse, called my book “The Attention Economy” and sent readers to the wrong one.)

Of course, calling customers gods is hyperbole: exaggeration for effect.  VRM has always been about customers coming to companies as equals. The “revolution in personal empowerment” in the subhead of “The Customer as a God” is about equality, not supremacy. For more on that, see the eleven posts before this one that mention the R-button:

That symbol (or pair of symbols) is about two parties who attract each other (like two magnets) and engage as equals. It’s a symbol that only makes full sense in open markets where free customers prove more valuable than captive ones. Not markets where customers are mere “targets” to “acquire,” “capture,” “manage,” “control” or “lock in” as if they were slaves or cattle.

The stage of Internet growth called Web 2.0 was all about those forms of capture, control, and coerced dependency. We’re still in it. (What’s being called Web3 is, while “decentralized” (note: not distributed), it is also based on tokens and blockchain. ) Investment in customer independence rounds to nil.

And that’s probably the biggest reason intentcasting as we imagined it in the first place has not taken off. It is very hard, inside industrial-age business norms (which we still have) to see customers as equals, or as human beings who should be equipped to lead in the dance between buyers and sellers, or demand and supply, in truly open marketplaces. It’s still easier to see us as mere consumers (which Jerry Michalski calls “gullets with wallets and eyeballs”).

So, where is there hope?

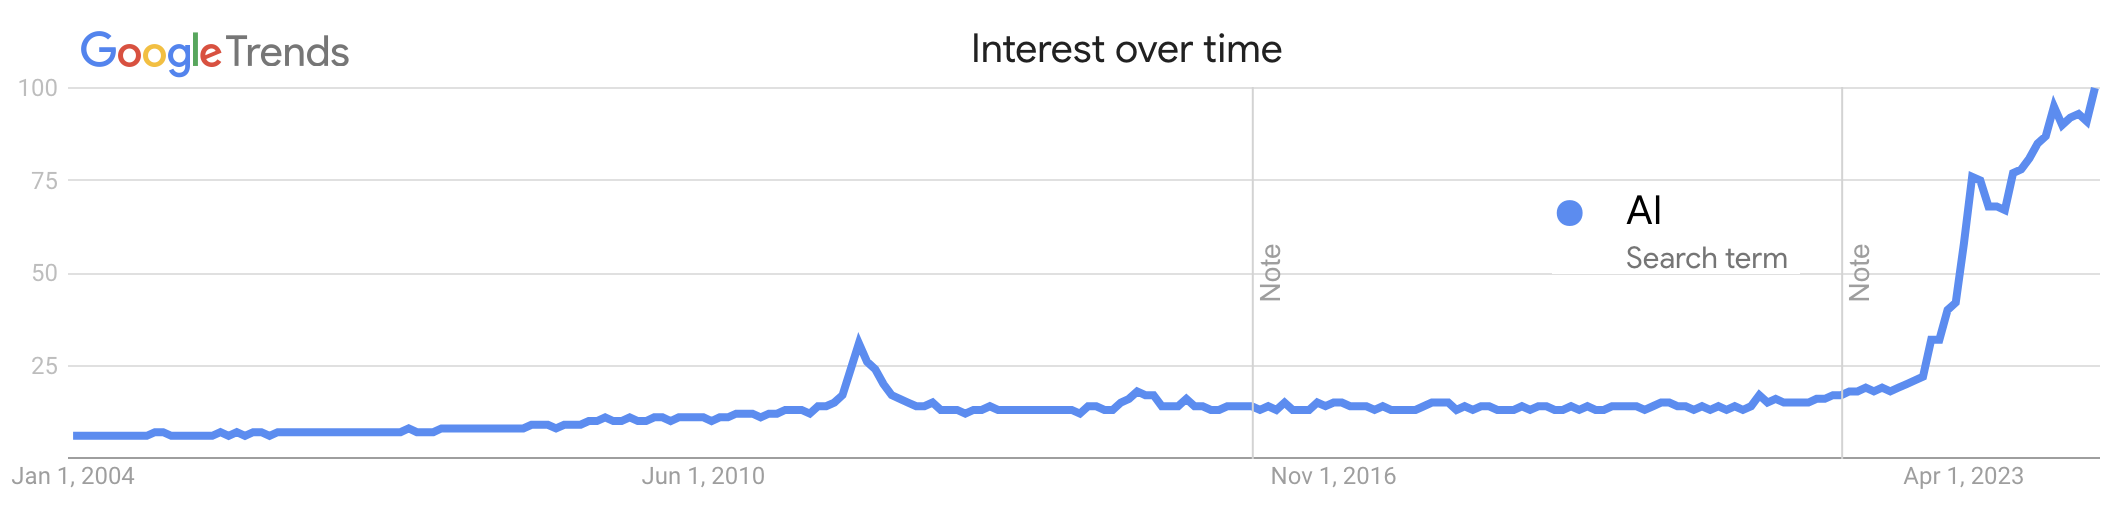
How about AI? It’s at the late end of its craze stage, but still here to stay, and hot as ever:

Can AI provide the “revolution in personal empowerment” we’ve been looking for here since 2006? Can it prove our thesis—that free customers are more valuable than captive ones—to themselves and to the marketplace?

Only if it’s personal.

If it is, then the market is a greenfield.

Some of us here are working at putting AI on both sides of intentcasting ceremonies. If you have, or know about, one or more of those approaches (or any intentcasting approaches), please share what you know, or what you’re got, in the comments below. And come to VRM Day on October 28. I’ll be putting up the invite for that shortly.


Up Starting

Not finishing up, or starting up, but up starting.unfinished stairs

Hell, we’ve been up and starting for one month short of eighteen years. Across that whole time, we’ve been pushing the idea that free customers are more valuable—to themselves, to sellers, to the whole marketplace—than captive ones.

And I’m more optimistic than ever that we’ll prove that idea in the next few years.

Toward that ambition, here are some links in tabs I’m closing:

That’s it for now.

The Personal AI Greenfield

What forms of pAI—personal AI—are Apple, Mozilla, Google, Meta, Microsoft and the rest not doing?

Let’s look at those first two because they’re at the top of the news LIFO buffer.

Apple Intelligence (“coming in beta this fall*“), announced yesterday, will help you with writing and creating images while giving you less lame answers from Siri. (Which they should re-name. Siri is Apple’s Clippy.) It “can draw on larger server-based models, running on Apple silicon, to handle more complex requests for you while protecting your privacy.” The “larger models” will be white-labeled ChatGPT, plus Apple’s own small language models (SLMs).

Mozilla, which got $400+ million a year from Google (for search in the Firefox browser) starting in 2020, announce on June 3 that they will be Building open, private AI with the Mozilla Builders Accelerator. Jive:

This program is designed to empower independent AI and machine learning engineers with the resources and support they need to thrive. It aims to cultivate a more innovative AI ecosystem, and it’s one of Mozilla’s key initiatives to make AI meaningfully impactful — alongside efforts like Mozilla.ai, the Responsible AI Challenge and the Rise25 Awards.

The Mozilla Builders Accelerator’s inaugural theme is local AI, which involves running AI models and applications directly on personal devices like laptops, smartphones, or edge devices rather than depending on cloud-based services…

We chose Local AI as the theme for the Accelerator’s first cohort because it aligns with our core values of privacy, user empowerment, and open source innovation. This method offers several benefits including:

  • Privacy: Data stays on the local device, minimizing exposure to potential breaches and misuse.
  • Agency: Users have greater control over their AI tools and data.
  • Cost-effectiveness: Reduces reliance on expensive cloud infrastructure, lowering costs for developers and users.
  • Reliability: Local processing ensures continuous operation even without internet connectivity.

Looks to me like both of these are Big AI writ small. It’s “local,” not personal. It’s made to serve your needs with what BigAI offers through APIs. It is still essentially AIaaS (AI as a Service), rather than truly personal AI (pAI): personalized more than personal.

That’s also what I see when I read between the lines at Mozilla’s AI job openings. Take platform engineer. This person will (among other things), “assist in managing and orchestrating workloads across multiple cloud providers.” That’s fine. I’m sure true pAIs will do that too. But most of pAI will be more personal than that. It will deal with the mundanities of your everyday life. Not with coughing up answers that can only come from AIaaSes.

The problem with personalizing AI giant offerings is that they are large language models (LLM) trained on everything that can be crawled on the Internet, plus who knows what else. Not on your truly personal stuff. This is why “prompt engineering” worthy of the noun is ” not for anybody:

Prompt engineering is crucial for deploying LLMs but is poorly understood mathematically. We formalize LLM systems as a class of discrete stochastic dynamical systems to explore prompt engineering through the lens of control theory. We investigate the reachable set of output token sequences $R_y(\mathbf x_0)$ for which there exists a control input sequence $\mathbf u$ for each $\mathbf y \in R_y(\mathbf x_0)$ that steers the LLM to output $\mathbf y$ from initial state sequence $\mathbf x_0$. We offer analytic analysis on the limitations on the controllability of self-attention in terms of reachable set, where we prove an upper bound on the reachable set of outputs $R_y(\mathbf x_0)$ as a function of the singular values of the parameter matrices. We present complementary empirical analysis on the controllability of a panel of LLMs, including Falcon-7b, Llama-7b, and Falcon-40b. Our results demonstrate a lower bound on the reachable set of outputs $R_y(\mathbf x_0)$ w.r.t. initial state sequences $\mathbf x_0$ sampled from the Wikitext dataset. We find that the correct next Wikitext token following sequence $\mathbf x_0$ is reachable over 97% of the time with prompts of $k\leq 10$ tokens. We also establish that the top 75 most likely next tokens, as estimated by the LLM itself, are reachable at least 85% of the time with prompts of $k\leq 10$ tokens. Intriguingly, short prompt sequences can dramatically alter the likelihood of specific outputs, even making the least likely tokens become the most likely ones. This control-centric analysis of LLMs demonstrates the significant and poorly understood role of input sequences in steering output probabilities, offering a foundational perspective for enhancing language model system capabilities.

But all that stuff applies mostly when we’re prompting a big LLM system.

What about using AI in our own lives, where the data that matters most are in our calendars, contacts, financial and health records, our travels, our correspondence (email, chat, whatever)? And how about all the location data we might get from our cars, phone apps, and phone companies? These should be much easier for a pAI to gather, examine, and help us do useful things. Caring about much less data also means a pAI will be less likely to give wrong (hallucinated) answers.

Today the mental frame almost everybody uses for AI is the Big kind, ingesting everything they can get their crawlers on, and munching all of it in giant compute farms. Those systems are great for lots of stuff, but they still don’t deal with personal data listed in the last paragraph.

Not yet, anyway.

Look at it this way. For each of us, there are three data pools:

  1. The entire Net, which is what gets crawled by all the giant LLM operators, plus whatever else they can get their claws on.
  2. One’s personal life, some of which is digitized in useful form (contacts, calendar, mail, stuff in folders inside PCs and attached drives).
  3. Personal data that is in the hands of giants, but is rightfully ours. These include our driving record and driving practices (,recorded by our late model cars and snitched to insurance companies and others), our location data (kept and shared by car and phone carriers to the likes of Google and the feds), our TV viewing habits, (gathered by Google, Amazon, Roku, Apple, etc.).

The pAI greenfield is with the last two.

Tell us who is working on what there, preferably with open source, and not sitting on walled garden silicon.

[Later… ] Since readers told me I had small language models (SLMs) wrong in one of the paragraphs above, and I’m not sure I had them right, I rewrote them out of the piece. I invite readers to post comments to further correct and expand on the subject of pAIs and what they can do.

Personal AI +/vs Corporate AI

Are they going to shake hands or fight? We’ll answer that question after personal AI exists and operates as a powerful personal agent.

You’re reading this on a machine with an operating system: Linux, Windows, MacOS, iOS, or Android.

But that’s not your OS. It’s your machine’s.

How about one for you, that runs on your machine but is entirely yours? Let’s call it a Personal OS, or a POS.

The POS will have a kernel onto which abilities (not just applications) can be added. An extreme example of how this might work is Neo learning ju jitsu in The Matrix:

That OS amplified Neo’s own intelligence, in his own head. We’re far from that today. But we can at least add abilities to a POS of our own. Those too can give us more agency of many kinds.

To my knowledge, there is only one POS so far. It’s called pAI-OS (Github code), and it’s led by Kwaai.* To my knowledge, pAI-OS is the first and only truly personal operating system. (If others do the same, let me know and I’ll talk those up too.) And it is built to run our own AIs. Let’s call them PAIs, where the A can mean amplified or augmented (sourcing Doug Englebart for the latter).

So, what kind of abilities are we talking about?

Let’s start with something that could hardly be more mundane and important: memory.

In Laws of Media, Marshall McLuhan (five decades ago) said that computing promises “perfect memory—total and exact.” For many millennia, our species has been outboarding memory through speech, and the written word, and collecting all of that in libraries and museums. And now, in the digital age that dawned with microcircuits and the Internet, we now occupy a digital world where everybody can publish whatever they want. To peruse that, we made search engines. Those ruled from the late ’90s until approximately yesterday, when AIs took over servicing our interest in answers to questions. Google, Microsoft, ChatGPT, Perplexity.ai, and others have moved into a space we might call AI answerware.

Running all that answerware are corporate AIs. Let’s call them CAIs. Nothing wrong with CAIs, but also nothing personal, because they are not ours. I explain the difference in Personal vs. Personalized AI. Here’s a graphic from that post showing a bit of what abilities might run on your PAI:

PAIs can extend our own memories by accumulating personal stuff we need to know better, and our ability to meet, access, and use the external abilities of the CAI world. So we’ll have our agents + their agents, working together.

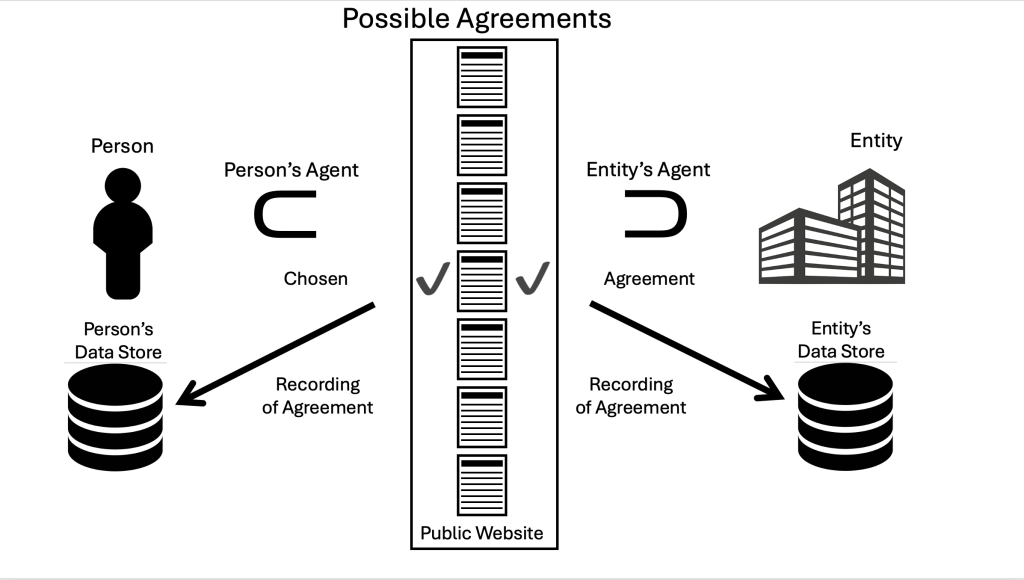
For an example of how that might work, take a look at The most important standard in development today: P7012: Standard for Machine Readable Personal Privacy Terms, which “identifies/addresses the manner in which personal privacy terms are proffered and how they can be read and agreed to by machines.” After seven years with a working group, it is now in the IEEE editing and approval mill, edging toward becoming a finished standard by next year. It works like this:

Here your agent (a PAI, represented by the ⊂ symbol) proffers your privacy terms (here is one example) to a corporate agent (which might or might not be a CAI, but is still represented with the reciprocal symbol ⊃. (This should be familiar to ProjectVRM veterans as the r-button. We may finally get to use it!)

The ceremony here is the exact reverse of what we have today with the cookie popovers on most website home pages. This can and should be done ⊂ to ⊃. So should signing and recording the agreement, or the choice of the site, should it tell you to screw off. (An agent running on your PAI will record that diss.)

I also bring this up because it will be a key required ability—not just for you and me but for the world, starting with Europe, where the GDPR lists six lawful bases for processing personal data. They begin—

(a) Consent: the individual has given clear consent for you to process their personal data for a specific purpose.
(b) Contract: the processing is necessary for a contract you have with the individual, or because they have asked you to take specific steps before entering into a contract.

By now everyone knows that (a) Consent has failed. It’s an expensive and meaningless dance, with high cognitive (mostly cynical) overhead, and almost no accountability. Now they’re ready for (b) Contract, especially in ceremonies where the individual (not a mere “user”) takes the lead.

I believe there is less limit to what each of us can do with a PAI than there is to what we can do with a laptop or a phone. Because our PAI is our own. It runs on a deeper machine OS, but is not limited by that. Your PAI, running on your POS, may prove to be the first truly personal layer ever put on a machine OS.


*Full disclosure: I am now the Chief Intention Officer there. At this stage, it’s a voluntary position.

Survey Hell

On a scale of one to ten, how do you rate the  Customer Experience Management (CEM) business?

I give it a zero.

Have you noticed that every service comes with a bonus survey—one you answer on a phone or fill out on a Web page? And that every one of those surveys is about rating the poor soul you spoke to or chatted with, rather than the company’s own crappy CEM system?

I always say yes to the question “Was your problem resolved?” because I know the human I spoke to will be punished if I say no.  Saying yes to that question complies with Don Marti‘s tweeted advice: “5 stars for everyone always—never betray a human to the machines.”

The main problem with CEM is that it’s all about getting service to scale across populations by faking interest in human contact. You can see it all through McKinsey’s The CEO Guide to Customer Experience. The customer is always on a “journey” through which a company has “touchpoints.”

Oh please.

IU Health, my primary provider of health services, does a good job on the whole, but one downside is the phone survey that follows up seemingly every interaction I have with a doctor or an assistant of some kind. The survey is always from a robot that says it “will only take a few minutes.” I haven’t counted, but I am sure some of those surveys last longer than the interaction I had with the human who provided the service: an annoyingly looooong touchpoint.

I wrote Why Surveys Suck here, way back in 2007. In it, I wrote,  “One way we can gauge the success of VRM is by watching the number of surveys decline.”

Makes me cringe a bit, but I think it’s still true.


The image above was created by Bing Creator and depicts “A hellscape of unhappy people, some on phones and others filling out surveys.”

Personal AI at VRM Day and IIW

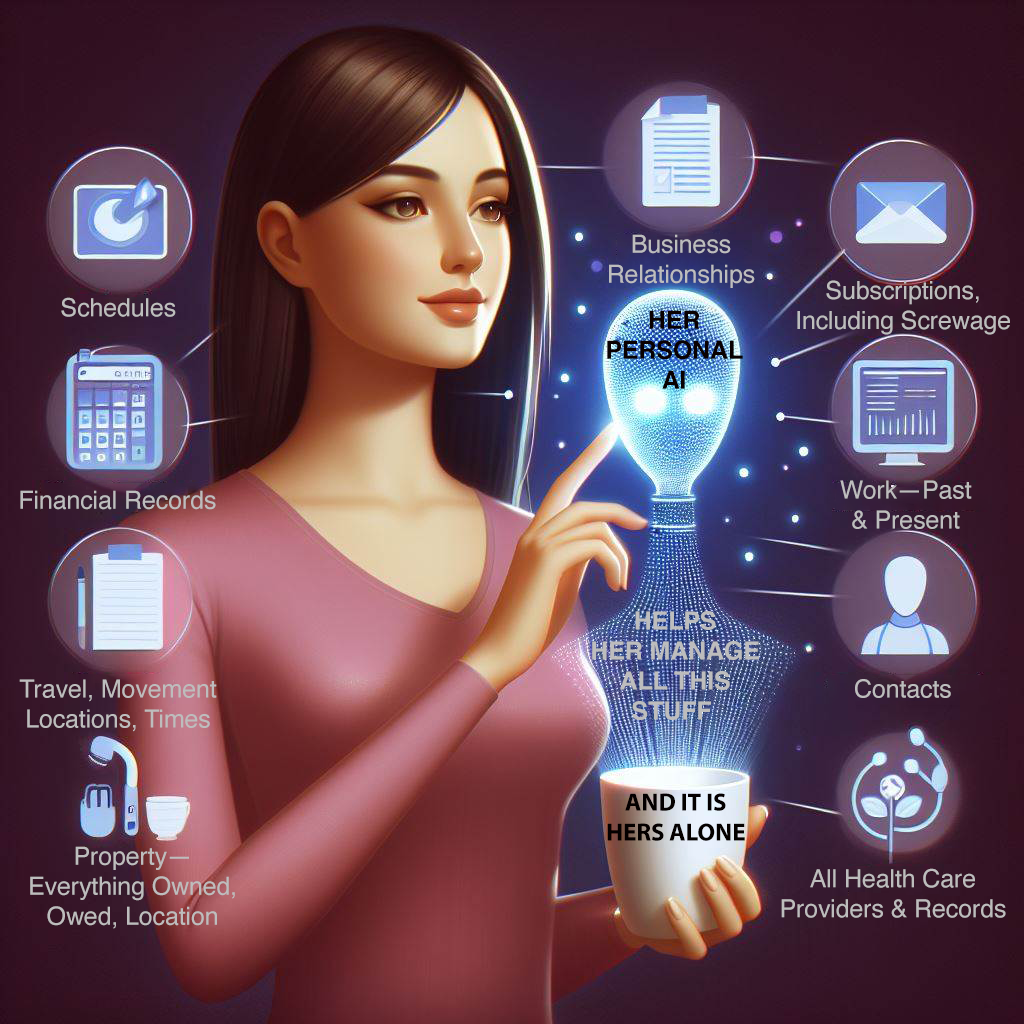
Prompt: A woman uses personal AI to know, get control of, and put to better use all available data about her property, health, finances, contacts, calendar, subscriptions, shopping, travel, and work. Via Microsoft Copilot Designer, with spelling corrections by the author.

Most AI news is about what the giants (OpenAI/Microsoft, Meta, Google/Apple, Amazon, Adobe, Nvidia) are doing (seven $trillion, anyone?), or what AI is doing for business (all of Forbes’ AI 50). Against all that, personal AI appears to be about where personal computing was in 1974: no longer an oxymoron but discussed more than delivered.

For evidence, look up “personal AI.” All the results will be about business (see here and here) or “assistants” that are just suction cups on the tentacles of giants (Siri, Google Assistant, Alexa, Bixby), or wannabes that do the same kind of thing (Lindy, Hound, DataBot).

There may be others, but three exceptions I know are Kin, Personal AI and Pi.

Personal AI is finding its most promoted early uses on the side of business more than the side of customers. Zapier, for example, explains that Personal AI “can be used as a productivity or business tool.”

Kin and Pi are personal assistants that help you with your life by surveilling your activities for your own benefit. I’ve signed up for both, but have only experienced Pit,” or “just vent,” when I ask it to help me with the stuff outlined in (and under) the AI-generated image above, it wants to hook me up with a bunch of siloed platforms that cost money, or to do geeky things (PostgreSQL, MongoDB, Python on my own computer. Provisional conclusion: Pi means well, but the tools aren’t there yet. [Later… Looks like it’s going to morph into some kind of B2B thing, or be abandoned outright, now that Inflection AI’s CEO, Mustafa Suleyman is gone to Microsoft. Hmm… will Microsoft do what we’d like in this space?]

Open source approaches are out there: OpenDAN, Khoj, Kwaai , and Llama are four, and I know at least one will be at VRM Day and IIW.

So, since personal AI may finally be what pushes VRM into becoming a Real Thing, we’ll make it the focus of our next VRM Day.

As always, VRM Day will precede IIW in the same location: the Boole Room of the Computer History Museum in Mountain View, just off Highway 101 in the heart of Silicon Valley. It’ll be on Monday, 15 April, and start at 9am. There’s a Starbucks across the street and ample parking because the museum is officially closed on Mondays, but the door is open. We lunch outdoors (it’s always clear) at the sports bar on the other corner.

Registration is open now at this Eventbrite link:

https://vrmday2024a.eventbrite.com

You can also just show up, but registering gives us a rough headcount, which is helpful for bringing in the right number of chairs and stuff like that.

See you there!


On Customer Constituency

A customer looks at a market where choice rules and nobody owns anybody. Source: Microsoft Copilot | Designer

I’m in a discussion of business constituencies. On the list (sourced from the writings of Doug Shapiro) are investors, employees, suppliers, customers, and regulators.

The first three are aware of their membership, but the last two? Not so sure.

Since ProjectVRM works for customers, let’s spin the question around. Do customers have a business constituency? If so, businesses are members by the customer’s grace. She can favor, ignore, or more deeply engage with any of those businesses at her pleasure. She does not “belong” to any of them, even though any or all of them may refer to her, or their many other customers, with possessive pronouns.

Take membership (e.g. Costco, Sam’s Club) and loyalty (CVS, Kroger) programs off the table. Membership systems are private markets, and loyalty programs are misnomered. (For more about that, read the “Dysloyalty” chapter of The Intention Economy.)

Let’s look instead at businesses that customers engage as a matter of course: contractors, medical doctors, auto mechanics, retail stores, restaurants, clubs, farmers’ markets, whatever. Some may be on speed dial, but most are not. What matters in all cases is that these businesses are responsible to their customers. “The real and effectual discipline which is exercised over a workman is that of his customers,” Adam Smith writes. “It is the fear of losing their employment which restrains his frauds and corrects his negligence.” That’s what it means to be a customer’s constituent.

An early promise of the Internet was supporting that “effectual discipline.” For the most part, that hasn’t happened. The “one clue” in The Cluetrain Manifesto said “we are not seats or eyeballs or end users or consumers. we are human beings and our reach exceeds your grasp. deal with it.” Thanks to ubiquitous surveillance and capture by corporate giants and unavoidable platforms, corporate grasp far outreaches customer agency.

That’s one reason ProjectVRM has been working against corporate grasp since 2006, and just as long for customer reach. Our case from the start has been that customer independence and agency are good for business. We just need to prove it.

An Approach to Paying for Everything That’s Free

Prompt: “A public marketplace for digital goods where people pay whatever they please for everything they consume.” Via Microsoft Image Creator

Now that we’ve hit peak subscription, and paywalls are showing up in front of formerly free digital goods (requiring, of course, more subscriptions), perhaps the world is ready for EmanciPay, an idea that has been biding its time on our wiki since 2009.

So, rather than leave it buried there, we’ll surface it here. Dig:::

Overview

Simply put, Emancipay makes it easy for anybody to pay (or offer to pay) —

  1. as much as they like
  2. however they like
  3. for whatever they like
  4. on their own terms

— or at least to start with that full set of options, and to work out differences with sellers easily and with minimal friction.

Emancipay turns consumers (aka users) into customers by giving them a pricing gun (something which in the past only sellers used) and their own means to make offers, to pay outright, and to escrow the intention to pay when price and other requirements are met. And to be able to do this at scale across all sellers, much as cash, browsers, credit cards, and email clients do the same. Payments themselves can also be escrowed.

In slightly more technical terms, EmanciPay is a payment framework for customers operating with full agency in the open marketplace, and at scale. It operates on open protocols and standards, so it can be used by any buyer, seller or intermediary.

It was conceived as a way to pay for music, journalism, or what any artist brings into the world. But it can apply to anything. For example, [subscriptions], have become a giant fecosystem in which every seller has separate and non-substitutable scale across all subscribers, while subscribers have zero scale across all sellers, with the highly conditional exceptions of silo’d commercial intermediaries. As [Customer Commons] puts it,

There’s also not much help coming from the subscription management services we have on our side: Truebill, Bobby, Money Dashboard, Mint, Subscript Me, BillTracker Pro, Trim, Subby, Card Due, Sift, SubMan, and Subscript Me. Nor from the subscription management systems offered by Paypal, Amazon, Apple or Google (e.g. with Google Sheets and Google Doc templates). All of them are too narrow, too closed and exclusive, too exposed to the surveillance imperatives of corporate giants, and too vested in the status quo.

That status quo sucks (see here, or just look up “subscription hell”), and it’s way past time to unscrew it.) But how?

The better question is where?

The answer to that is on our side: the customer’s side.

While EmanciPay was first conceived by ProjectVRM as a way to make live payments to nonprofits and to provide a new monetization method for publishers. it also works as a counterpart to sellers’ subscription systems in what Zuora (a supplier of subscription management systems to the publishing industry, including The Guardian and Financial Times) calls the “subscription economy“, which it says “is built on ever-changing relationships with your customers”. Since relationships are two-way by nature, EmanciPay is one way that customers can manage their end, while publisher-side systems such as Zuora’s manage the other.

Emancipay economic case

EmanciPay provides a new form of economic signaling not available to individuals, either on the Net or before the Net became available as a communications medium. EmanciPay will use open standards and be comprised of open-source code. While any commercial fourth parties can use EmanciPay (or its principles, or any parts of it they like), EmanciPay’s open and standard framework will support fourth parties by making them substitutable, much as the open standards of email (SMTP, POP3, IMAP) make email systems substitutable. (Each has what Joe Andrieu calls service endpoint portability.)

EmanciPay is an instrument of customer independence from all of the billion (or so) commercial entities on the Net, each with its own arcane and siloed systems for engaging and managing customer relations, as well as receipt, acknowledgment, and accounting for payments from customers.

Use Case Background

EmanciPay was conceived originally as a way to provide customers with the means to signal interest and the ability to pay for media and creative works (most of which are freely available on the Web, if not always free of charge). Through EmanciPay, demand and supply can relate, converse, and transact business on mutually beneficial terms, rather than only on terms provided by the countless different siloed systems we have today, each serving to hold the customer captive, and causing much inconvenience and friction in the process.

Media goods were chosen for five reasons: 1) because most are available for free, even if they cost money, or are behind paywalls 2) paywalls, which are cookie-based, cannot relate to individuals as anything other than submissive and dependent parties (and each browser a users employs carries a different set of cookies) 3) both media companies and non-profits are constantly looking for new sources of revenue 4) the subscription model, while it creates steady income and other conveniences for sellers, is often a bad deal for customers, and is now so overused (see Subscriptification) that the world is approaching a peak subscription crisis, and unscrewing it can only happen from the customer’s side (because the business is incapable of unscrewing the problem itself 5) all methods of intermediating payment choices are either siloed by the seller or siloed by intermediators, discouraging participation by individuals.

What the marketplace requires are new business and social contracts that ease payment and stigmatize non-payment for creative goods. The friction involved in voluntary payment is still high, even on the Web, where one must go through complex ceremonies even to make simple payments. There is no common and easy way either to keep track of what media (free or otherwise) we use (see Media Logging), to determine what it might be worth, and to pay for it easily and in standard ways — to many different suppliers. (Again, each supplier has its own system for accepting payments.)

EmanciPay differs from other payment models (subscriptions, newsstands, tip jars) by providing customers with the ability to choose what they wish to pay and how they’ll pay it, with minimum friction — and with full choice about what they disclose about themselves.

EmanciPay will also support credit for referrals, requests for service, feedback, and other relationship support mechanisms, all at the control of the user. For example, EmanciPay can provide quick and easy ways for listeners to pay for public radio broadcasts or podcasts, for readers to pay for otherwise “free” papers or blogs, for listeners to pay to hear music and support artists, for users to issue promises of payment for stories or programs — all without requiring the individual to disclose unnecessary private information or to become a “member” — although these options are kept open.

This will scaffold genuine relationships between buyers and sellers in the media marketplace. It will also give deeper meaning to “membership” in non-profits. (Under the current system, “membership” generally means putting one’s name on a pitch list for future contributions, and not much more than that.)

EmanciPay will also connect the sellers’ CRM (Customer Relationship Management) systems with customers’ VRM (Vendor Relationship Management) systems, supporting rich and participatory two-way relationships. In fact, EmanciPay will by definition be a VRM system.

Micro-accounting and Macro-distribution

The idea of “micro-payments” for goods on the Net has been around for a long time and is often brought up as a potential business model for journalism. For example in this article by Walter Isaacson in Time Magazine. It hasn’t happened, at least not globally, because it’s too complicated, and in prototype only works inside private silos.

What ProjectVRM suggests instead is something we don’t yet have, but very much need:

  1. micro-accounting for actual uses. Think of this simply as “keeping track of” the news, podcasts, newsletters, or music we consume.
  2. macro-distribution of payments for accumulated use (that’s no longer “micro”).

Much — maybe most — of the digital goods we consume are both free for the taking and worth more than $zero. How much more? We need to be able to say. In economic terms, demand needs to have a much wider range of signals it can give to supply. And give to each other, to better gauge what we should be willing to pay for free stuff that has real value but not a hard price.

As currently planned, EmanciPay would –

  1. Provide a single and easy way for consumers of “content” to become customers of it. In the current system — which isn’t one — every artist, every musical group, and every public radio and TV station has his, her or own way of taking in contributions from those who appreciate the work. This can be arduous and time-consuming for everybody involved. (Imagine trying to pay separately every musical artist you like, for all your enjoyment of each artist’s work.) What EmanciPay proposes, however, is not a replacement for existing systems, but a new system that can supplement existing fund-raising systems — one that can soak up much of today’s MLOTT: Money Left On The Table.
  2. Provide ways for individuals to look back through their media usage histories, inform themselves about what they have been enjoying, and determine how much it is worth to them. The Copyright Arbitration Royalty Panel (CARP), and later the Copyright Royalty Board (CRB), both came up with “rates and terms that would have been negotiated in the marketplace between a willing buyer and a willing seller.” This almost absurd language first appeared in the 1995 Digital Performance Royalty Act (DPRA) and was tweaked in 1998 by the Digital Millennium Copyright Act (DMCA), under which both the CARP and the CRB operated. The rates they came up with peaked at $.0001 per “performance” (a song or recording), per listener. EmanciPay creates the “willing buyer” that the DPRA thought wouldn’t exist.
  3. Stigmatize non-payment for worthwhile media goods. This is where “social” will finally come to be something more than yet another tech buzzmodifier.

All these require micro-accounting, not micro-payments. Micro-accounting can inform ordinary payments that can be made in clever new ways that should satisfy everybody with an interest in seeing artists compensated fairly for their work. An individual listener, for example, can say “I want to pay 1¢ for every song I hear,” and “I’ll send SoundExchange a lump sum of all the pennies wish to pay for songs I have heard over a year, along with an accounting of what artists and songs I’ve listened to” — and leave dispersal of those totaled pennies up to the kind of agency that likes, and can be trusted, to do that kind of thing. That’s the macro-distribution part of the system.

Similar systems can also be put in place for readers of newspapers, blogs, and other journals. What’s important is that the control is in the hands of the individual and that the accounting and dispersal systems work the same way for everybody.

« Older posts Newer posts »

© 2026 ProjectVRM

Theme by Anders Noren — Up ↑